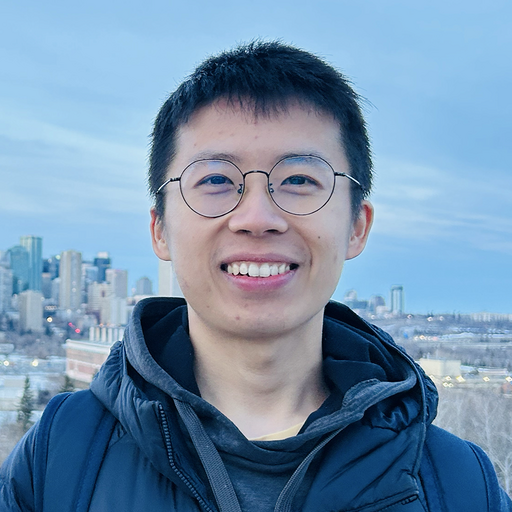
Jiamin He

I am a Ph.D. student in Computing Science at the University of Alberta, supervised by Martha White. I am a member of the RLAI lab and Amii. I completed an internship at Google DeepMind in London, where I worked with Diana Borsa and Hado van Hasselt on foundational reinforcement learning algorithms and their applications in science.

Previously, I received my M.Sc. degree in Computing Science at the University of Alberta under the supervision of Rupam Mahmood. Before that, I also worked with Chongjie Zhang as a research intern.

My research interests lie in online reinforcement learning, with a focus on policy optimization, off-policy learning, and temporal abstraction.

Email  /  Google Scholar  /  GitHub  /  Blog

Jiamin He

Publications

* denotes equal contribution.

Revisiting Mixture Policies in Entropy-Regularized Actor-Critic.
Jiamin He, Samuel Neumann, Jincheng Mei, Adam White, Martha White.
Preliminary version at the Aligning Reinforcement Learning Experimentalists and Theorists Workshop at NeurIPS, 2025.
TMLR, 2026.
paper

Off-policy Learning with Excursion Policies.
Jiamin He, Mark Rowland, Zhaohan Daniel Guo, Hado van Hasselt, Diana Borsa.
NeurIPS, 2026.
paper

Improving Reward-Based Hindsight Credit Assignment.
Aditya A. Ramesh, Jiamin He, Jürgen Schmidhuber, Martha White.
Preliminary version at the European Workshop on Reinforcement Learning, 2025.
RLJ, 2026.
paper | code

Extending Differential Temporal Difference Methods for Episodic Problems.
Kris De Asis, Mohamed Elsayed, Jiamin He.
RLJ, 2026.
paper

Forager: A Lightweight Testbed for Continual Learning with Partial Observability in RL.
Steven Tang, Xinze Xiong, Anna Hakhverdyan, Andrew Patterson, Jacob Adkins, Jiamin He, Esraa Elelimy, Parham Mohammad Panahi, Martha White, Adam White.
RLJ, 2026.
paper | code

Distributions as Actions: A Unified Framework for Diverse Action Spaces.
Jiamin He, A. Rupam Mahmood, Martha White.
Preliminary version at the Finding the Frame Workshop at RLC, 2025.
ICLR, 2026.
paper | code

Investigating the Utility of Mirror Descent in Off-policy Actor-Critic.
Samuel Neumann, Jiamin He, Adam White, Martha White.
RLJ, 2025.
paper | code

Deep Policy Gradient Methods Without Batch Updates, Target Networks, or Replay Buffers.
Gautham Vasan, Mohamed Elsayed, Alireza Azimi*, Jiamin He*, Fahim Shariar, Colin Bellinger, Martha White, A. Rupam Mahmood.
NeurIPS, 2024.
paper | code

Loosely Consistent Emphatic Temporal-Difference Learning.
Jiamin He, Fengdi Che, Yi Wan, A. Rupam Mahmood.
Preliminary version in the average-reward setting at the Deep RL Workshop at NeurIPS, 2022.
UAI, 2023.
paper | code

Episodic Multi-agent Reinforcement Learning with Curiosity-Driven Exploration.
Lulu Zheng*, Jiarui Chen*, Jianhao Wang, Jiamin He, Yujing Hu, Yingfeng Chen, Changjie Fan, Yang Gao, Chongjie Zhang.
NeurIPS, 2021.
paper | code

Theses

Consistent Emphatic Temporal-Difference Learning.
Jiamin He.
M.Sc. Thesis, University of Alberta, 2023.
details


Stolen from Jon Barron